<?xml version="1.0" encoding="UTF-8"?>
<?xml-stylesheet href="/vendor/feed/atom.xsl" type="text/xsl"?>
<feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en-US">
                        <id>https://ohdear.app/feed</id>
                                <link href="https://ohdear.app/feed" rel="self"></link>
                                <title><![CDATA[ohdear.app]]></title>
                    
                                <subtitle>The description of the feed.</subtitle>
                                                    <updated>2026-10-16T14:17:09+00:00</updated>
                        <entry>
            <title><![CDATA[The ghost domain problem in DNS, and what we're doing about it]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/the-ghost-domain-problem-in-dns-and-what-were-doing-about-it" />
            <id>https://ohdear.app/191</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>There's a DNS edge case that even people who know DNS well tend not to have run into: a domain pulled by its registry can keep appearing healthy to uptime checkers for days after it's gone. The .de zone triggers it when contact verification fails, and other registries have their own versions. We don't always catch it, and most other monitoring services don't either.</p>
<p>It's called the ghost domain problem. It's documented in DNS research circles and has an active IETF draft (<a href="https://datatracker.ietf.org/doc/draft-ietf-dnsop-ns-revalidation/">draft-ietf-dnsop-ns-revalidation</a>), but it's niche enough that an uptime product can run for years without anyone noticing it. This post is about why, and the small set of changes we're making on our end.</p>
<h2 id="how-it-shows-up">How it shows up <a href="#how-it-shows-up" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#how-it-shows-up">#</a></h2>
<p>The .de zone has a strict holder-data verification policy. If the registrant's details aren't verified within <a href="https://www.denic.de/en/products/holder-data-verification/general-information/">DENIC</a>'s deadline, DENIC first removes the domain from the .de zone and deletes it later. And .de is far from alone. <a href="https://eurid.eu/en/about-eurid/data-quality/">EURid</a> suspends a .eu domain and, if the data still isn't verified, moves it to a withdrawn (no longer registered) state. <a href="https://www.afnic.fr/en/domain-names-and-support/resolve-a-dispute/holder-eligibility-and-contact/">AFNIC</a> runs an eligibility and contactability check on .fr holders and can suspend, then eventually delete, a domain whose holder doesn't correct or substantiate their data.</p>
<p>And across ICANN gTLDs like .com, .net, and .org, the <a href="https://www.icann.org/resources/pages/non-response-2014-01-29-en">2013 WHOIS Accuracy Program</a> requires the registrar (not the registry) to suspend, terminate, or place a domain on <code>clientHold</code> after more than 15 days without a response to a verification request, which pulls it from zone publication. Failed verification, expired registration, registrar disputes, abuse takedowns: the names differ, the shape doesn't. The registry or registrar pulls the name from the parent zone, but the domain's own authoritative nameservers keep answering as if nothing changed.</p>
<p>For anyone whose resolver no longer holds the child-side records, that means NXDOMAIN (RCODE 3, &quot;name does not exist&quot;). A fat error in the address bar, no site. For an uptime checker sitting behind a long-lived recursive resolver cache that does still hold them, it can mean nothing at all. The difference isn't browser versus checker, it's a cold cache versus a warm one. The site looks fine. It isn't.</p>
<h2 id="where-the-bug-lives">Where the bug lives <a href="#where-the-bug-lives" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#where-the-bug-lives">#</a></h2>
<p>This was the DNS chain we had on one of our uptime workers (Frankfurt, in this case):</p>
<pre data-lang="txt" class="notranslate">PHP/curl
  → glibc nsswitch (files dns)
  → /etc/resolv.conf (127.0.0.53)
  → systemd-resolved stub
  → upstream recursive resolver (shared, run by the hosting provider)
  → authoritative nameservers (the domain's DNS provider)
</pre>
<p>I'll spare you the full diagnostic. The summary: <code>systemd-resolved</code> is a local caching stub. The real resolution work happens in a recursive resolver upstream, and that's where the bug lives. Not on our box, and not on yours. This is inherent to how recursive DNS works, no matter who runs the resolver: the caching layer that makes DNS fast is the same layer that can keep a dead delegation warm.</p>
<p>That detail matters. We could ship the most diligent uptime checker on the planet and still get the wrong answer, because we're trusting a cache we don't control.</p>
<h2 id="ghost-domains-briefly">Ghost domains, briefly <a href="#ghost-domains-briefly" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#ghost-domains-briefly">#</a></h2>
<p>The mechanism is documented in academic literature (the NDSS <a href="https://www.ndss-symposium.org/ndss2012/ndss-2012-programme/ghost-domain-names-revoked-yet-still-resolvable/">Ghost Domain Names</a> paper from 2012, and a 2023 follow-up <a href="https://www.ndss-symposium.org/ndss-paper/ghost-domain-reloaded-vulnerable-links-in-domain-name-delegation-and-revocation/">Ghost Domain Reloaded</a>). It currently sits in an active IETF draft, <a href="https://datatracker.ietf.org/doc/draft-ietf-dnsop-ns-revalidation/">Delegation Revalidation by DNS Resolvers</a>. The credibility rule it depends on is in <a href="https://datatracker.ietf.org/doc/rfc2181/">RFC 2181</a>, and the delegation-versus-glue terminology in <a href="https://www.rfc-editor.org/info/rfc9499">RFC 9499</a> (which obsoleted RFC 8499).</p>
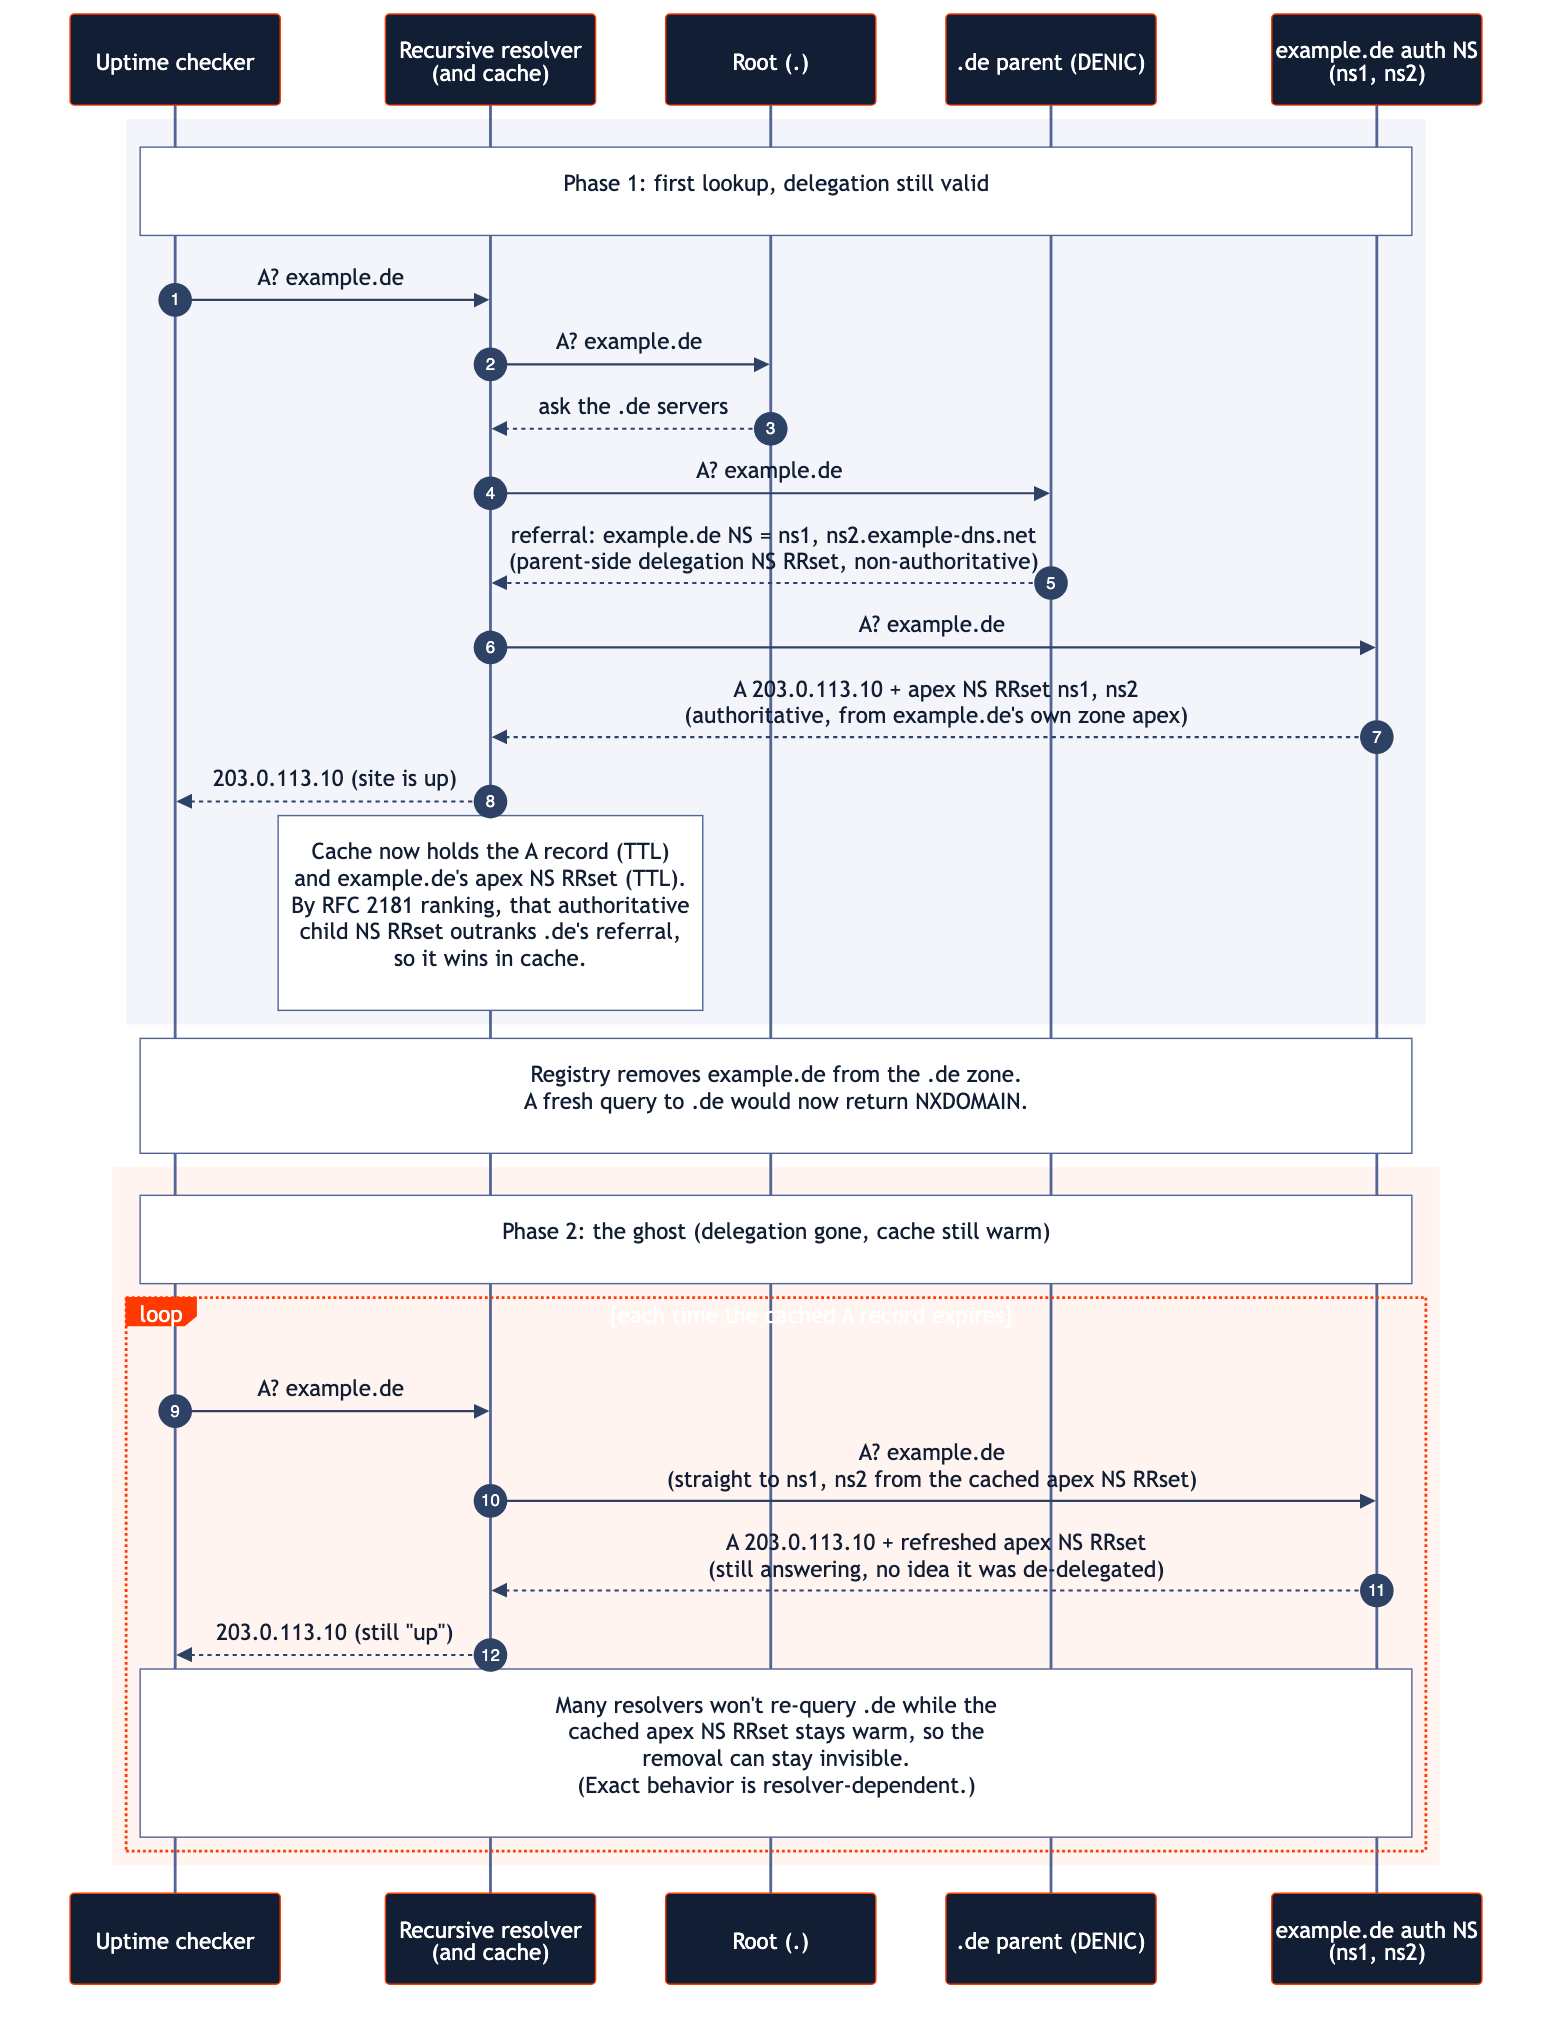
<p>Here's how it plays out, step by step:</p>
<p><img src="/media/blog/LzPcrqZtbDOd74uJwfRQOJjc3LqulGI798laNYR6.png" alt="DNS sequence diagram of the ghost domain problem showing resolvers still using a cached NS RRset after delegation is removed" /></p>
<h3 id="step-1-the-first-lookup">Step 1: The first lookup</h3>
<p>The first time a recursive resolver looks up <code>example.de</code>, it walks down to the <code>.de</code> (parent) servers, which hand back a referral: &quot;I don't host <code>example.de</code>, but its nameservers are <code>ns1.example-dns.net</code> and <code>ns2.example-dns.net</code>.&quot; That's the parent-side delegation NS RRset, the NS records <em>for</em> <code>example.de</code>, as published by <code>.de</code>.</p>
<p>The resolver then asks those nameservers directly, and their authoritative answer usually carries the same two-name list again, this time published by <code>example.de</code> itself from its own zone apex. That copy is the apex NS RRset. Auth servers aren't required to include it, but they usually do, and the ghost effect depends on it being cached.</p>
<h3 id="step-2-the-childs-copy-outranks-the-parents">Step 2: The child's copy outranks the parent's</h3>
<p>Both RRsets name the same two servers; the difference is who said so. Per RFC 2181's ranking rules, the child's authoritative apex copy (from <code>example.de</code>) outranks the parent's referral copy (from <code>.de</code>), so it replaces the parent-side one in cache. To be clear, this is the NS RRset for <code>example.de</code> itself, not the NS records of the <code>.de</code> zone.</p>
<h3 id="step-3-the-a-record-expires">Step 3: The A record expires</h3>
<p>Later, when the A record expires, the resolver asks &quot;where do I find example.de?&quot;, finds the cached apex NS RRset (still pointing at <code>ns1</code> and <code>ns2.example-dns.net</code>), and queries those nameservers directly.</p>
<h3 id="step-4-the-authoritative-servers-still-answer">Step 4: The authoritative servers still answer</h3>
<p>The authoritative nameservers still answer positively. They have no idea the registry pulled the delegation. Why would they?</p>
<h3 id="step-5-the-loop">Step 5: The loop</h3>
<p>A fresh A record gets cached. Another TTL window starts. Loop.</p>
<p>Absent any revalidation, the parent zone is ordinarily not consulted again as long as the apex NS RRset stays warm. And the defaults don't help:</p>
<table>
<thead>
<tr>
<th>Resolver</th>
<th>Cache window</th>
<th>Parent revalidation</th>
</tr>
</thead>
<tbody>
<tr>
<td>BIND</td>
<td><code>max-cache-ttl</code> = 1 week</td>
<td>No equivalent delegation-revalidation control</td>
</tr>
<tr>
<td>Unbound</td>
<td><code>cache-max-ttl</code> = 1 day</td>
<td><code>harden-referral-path</code> off by default</td>
</tr>
<tr>
<td>PowerDNS Recursor</td>
<td><code>max-cache-ttl</code> = 1 day</td>
<td><code>save-parent-ns-set</code> (a failure fallback, not revalidation)</td>
</tr>
<tr>
<td>systemd-resolved</td>
<td>caching stub, inherits upstream</td>
<td>n/a</td>
</tr>
</tbody>
</table>
<p>It's tempting to assume frequent uptime checks are what keep the cache hot. Not quite. What keeps a ghost alive is the resolver reacquiring the apex NS RRset before it ages out, and how long that RRset lives is bounded by its own TTL and the resolver's cap. Check frequency only matters as opportunities to reacquire it, so cutting back on checks won't save you: a domain with a long NS TTL can keep ghosting off very few lookups per cache window.</p>
<h2 id="what-every-other-monitoring-service-does">What every other monitoring service does <a href="#what-every-other-monitoring-service-does" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-every-other-monitoring-service-does">#</a></h2>
<p>I went looking. I read the public docs, FAQs, and architecture pages of Pingdom, UptimeRobot, StatusCake, Site24x7, Datadog Synthetics, and Better Stack.</p>
<p>I couldn't find a documented defense against this in any of their public materials.</p>
<p>Pingdom actually documents the architecture that <em>causes</em> the bug, in their <a href="https://www.pingdom.com/blog/pingdom-say-my-site-is-down/">own blog post</a>:</p>
<blockquote>
<p>Each of Pingdom's probe servers run their own individual Bind9 caching DNS server as their DNS resolver, so DNS records will be cached.</p>
</blockquote>
<p>We don't know how they've tuned it, and a per-probe BIND is a perfectly reasonable setup. But BIND's default <code>max-cache-ttl</code> is one week, and unless that's been lowered, it's exactly the kind of cache horizon where a ghost domain can stick around for days.</p>
<p>A few of these tools monitor domain expiry, and so do we: Oh Dear has <a href="https://ohdear.app/features/domain-monitoring">domain expiration monitoring</a> that warns you well before a renewal date slips past. But that's adjacent, not the same thing. Expiry monitoring watches the registration date, not whether a still-paid-for domain has been pulled from the zone over a failed verification. I couldn't find any tool, ours included, that treats registry-level delegation removal as a distinct case in its uptime checks.</p>
<p>This isn't a gotcha against any of them. It stayed off our radar for the same reason it probably has for theirs: it's a DNS-layer problem hiding under an HTTP-layer product, invisible until someone goes looking.</p>
<h2 id="what-were-tightening">What we're tightening <a href="#what-were-tightening" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-were-tightening">#</a></h2>
<p>We're keeping this narrow.</p>
<p><strong>A local recursive resolver on each checker, with a tight cache.</strong> We're running <a href="https://nlnetlabs.nl/projects/unbound/about/">Unbound</a> on each worker, doing full recursion itself instead of forwarding to a shared upstream resolver. The point isn't &quot;ours is better.&quot; It's that we get to set the knobs.</p>
<p>Two of them matter here:</p>
<table>
<thead>
<tr>
<th>Knob</th>
<th>Default</th>
<th>Our setting</th>
<th>Why</th>
</tr>
</thead>
<tbody>
<tr>
<td><code>cache-max-ttl</code></td>
<td>1 day</td>
<td>1 hour</td>
<td>Caps how long a stale apex NS RRset can ghost a domain</td>
</tr>
<tr>
<td><code>harden-referral-path</code></td>
<td>off</td>
<td>on</td>
<td>Re-checks NS data along the referral path, not just cache</td>
</tr>
</tbody>
</table>
<p>Unbound caps cached records at a day by default; we clamp that to an hour. Once the cached apex NS RRset expires, the next lookup has to restart iteration from the closest cached cut, typically the TLD's nameservers, to find the delegation again, and that's exactly where a pulled delegation now comes up empty. <code>harden-referral-path</code> (paired with a deeper <code>target-fetch-policy</code>, as the Unbound docs recommend) makes the resolver re-check the NS data it meets on the way down instead of trusting stale child-side state.</p>
<p>That's the main change. It doesn't make ghost domains impossible, but it shortens the window in which a stale delegation can lie to us from days down to about an hour.</p>
<p>We've thought about heavier options. Cross-resolver verification on failed checks, where we'd cross-check with <code>1.1.1.1</code>, <code>8.8.8.8</code>, and <code>9.9.9.9</code> in parallel. Dedicated parent-zone delegation polling per monitored domain, à la <code>dig @f.nic.de example.de NS</code>. Both are real fixes, and we may come back to them. But the operational cost (extra DNS load, public resolver rate limits) is hard to justify when tightening our own resolver already covers the realistic cases.</p>
<h2 id="what-this-doesnt-fix">What this doesn't fix <a href="#what-this-doesnt-fix" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-this-doesnt-fix">#</a></h2>
<p>DNS caches exist for good reasons. The whole reason a recursive resolver works the way it does is to keep the global DNS from melting every time someone reloads a page. We're not going to &quot;fix DNS.&quot; What we can do is narrow the window where a stale delegation goes unnoticed.</p>
<p>If a ghost domain's apex NS RRset keeps refreshing inside our shorter cache window, it can still slip past us. Other layers (the registry's own propagation cadence, the authoritative DNS host, the resolvers downstream from us) all behave their own way. We're reducing surface area, not eliminating it.</p>
<p>And we're honest about the tools we reached for. <code>harden-referral-path</code> is experimental and not an RFC standard, so we run DNSSEC validation alongside it in permissive, log-only mode: bogus answers get logged for us to review, not turned into SERVFAIL, so a signing glitch on a customer's domain can't show up as false downtime. That's a deliberate first step. Once the logs stay clean and the rollout proves stable, we plan to flip DNSSEC to enforcing over the coming weeks.</p>
<h2 id="what-you-should-do">What you should do <a href="#what-you-should-do" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-you-should-do">#</a></h2>
<p>If you run anything important on a domain you don't own at the registrar level, run <a href="https://ohdear.app/features/dns-monitoring">DNS monitoring</a> alongside <a href="https://ohdear.app/features/website-uptime-monitoring">uptime monitoring</a>. Uptime monitoring answers &quot;can my site be reached?&quot; DNS monitoring answers &quot;is the DNS layer healthy?&quot; Together they catch problems neither one would on its own.</p>
<p>In Oh Dear, you turn DNS monitoring on per monitor in the <a href="https://ohdear.app/docs/features/dns-monitoring">DNS check settings</a>. It watches your A, AAAA, MX, NS, and TXT records and alerts when they drift. It's part of your plan, not a paid add-on: every monitoring check we offer is included, at no extra cost.</p>
<p>If you're not an Oh Dear customer yet, you can try it for 10 days, free, no credit card needed. And if you hit a monitoring edge case we don't catch yet, show us. We'll make Oh Dear better by building the fix in.</p>
]]>
            </summary>
                                    <updated>2026-06-12T08:58:01+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[Kickstarting our reseller program with Zone & Ploi Cloud]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/kickstarting-our-reseller-program-with-zone-ploi-cloud" />
            <id>https://ohdear.app/178</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>We've quietly been building a reseller program over the past months. The idea is simple: let hosting providers, deployment platforms, and agencies offer Oh Dear monitoring directly inside their own products. Not a stripped-down version, the full thing.</p>
<p>We're working with several partners to bring Oh Dear into more products and platforms. <strong>Zone</strong> and <strong>Ploi Cloud</strong> are the first two out the door.</p>
<h2 id="whats-the-reseller-program">What's the reseller program? <a href="#whats-the-reseller-program" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#whats-the-reseller-program">#</a></h2>
<p>If you run a hosting company, a deployment platform, or an agency managing client sites, you probably want monitoring baked into your product. Building that from scratch is a massive undertaking. <a href="/features/website-uptime-monitoring">Uptime checks</a> from multiple global locations, <a href="/features/continuous-certificate-monitoring">SSL monitoring</a>, <a href="/features/broken-page-and-mixed-content-detection">broken link detection</a>, <a href="/features/performance-monitoring">performance tracking</a>, <a href="/features/dns-monitoring">DNS change alerts</a>, <a href="/features/scheduled-task-monitoring">cron monitoring</a>... that's years of work.</p>
<p>Our reseller program lets you skip all of that. You integrate with our API, and your customers get the full Oh Dear experience inside your platform. You handle the billing and the relationship with your customer. We handle the monitoring infrastructure.</p>
<h2 id="zone-monitoring-as-a-native-hosting-feature">Zone: monitoring as a native hosting feature <a href="#zone-monitoring-as-a-native-hosting-feature" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#zone-monitoring-as-a-native-hosting-feature">#</a></h2>
<p><img src="/media/blog/WHELmtLHKPGKe4otH84lJNVwfPD6mSAUZCKpYNCs.webp" alt="Zone promo image of a man leaping mid-air with bold text 'Oh Dear! Less stress, more time' and the Zone logo" /></p>
<p><a href="https://www.zone.eu/">Zone</a> is one of the largest domain registration and hosting providers in the Baltics, operating in <a href="https://www.zone.ee/et/">Estonia</a>, <a href="https://www.speedzone.fi/fi/">Finland</a> and <a href="https://www.zone.lv/lv/">Latvia</a>. They now offer Oh Dear monitoring as a native service to all their customers, covering uptime, SSL certificates, broken links, performance, domain expiry, DNS changes, and cron job monitoring.</p>
<p>Their approach to <a href="/features/notifications">notifications</a> is seamless: Zone customers get a one-click login into the full Oh Dear dashboard, where they can configure exactly which alerts they want and where they should go. Email, SMS, Slack, webhooks, you name it. The customer controls their own notification preferences directly in Oh Dear, without ever needing to create a separate account.</p>
<p>What we love about Zone's integration: they don't just resell it, they use Oh Dear internally too. When your own hosting provider trusts the same monitoring tool they're offering you, that says something.</p>
<blockquote>
<p>&quot;Oh Dear is the easy one to implement, because the API makes sense and is easy to work with.&quot;</p>
<p>Kaarel Urva, Chief Project Officer at Zone Media</p>
</blockquote>
<p>You can read more about their offering in <a href="https://www.zone.eu/blog/oh-dear-a-simple-way-to-truly-understand-how-your-website-is-doing/">Zone's announcement post</a>.</p>
<h2 id="ploi-cloud-three-clicks-to-monitoring">Ploi Cloud: three clicks to monitoring <a href="#ploi-cloud-three-clicks-to-monitoring" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#ploi-cloud-three-clicks-to-monitoring">#</a></h2>
<p><img src="/media/blog/eYJtt6XwqpJhMC5dQYvOzgMVnPxeOZrucAyXngDD.png" alt="Ploi Cloud and Oh Dear logos linked by a heart, announcing a partnership for uptime monitoring in Ploi Cloud" /></p>
<p><a href="https://ploi.cloud">Ploi Cloud</a> is a deployment platform built for developers. Their Oh Dear integration is beautifully simple: navigate to the Monitoring tab, click &quot;Enable monitoring&quot;, and you're done. Uptime checks, SSL monitoring, performance metrics, broken link detection, and mixed content scanning, all running within seconds.</p>
<p>Ploi took a different approach to notifications. Instead of sending users to the Oh Dear dashboard, they receive all monitoring alerts through our <a href="/docs/tools-and-sdks/webhooks">webhooks</a> and pipe them into their existing notification system. If you've already set up Slack, Discord, Google Chat, or email notifications in Ploi, your monitoring alerts just show up there too. Nothing extra to configure.</p>
<p>Their team described it well: &quot;This isn't a third-party plugin or a workaround, it's a first-class integration built together.&quot;</p>
<p>Check out <a href="https://ploi.cloud/blog/introducing-uptime-monitoring-powered-by-oh-dear">Ploi Cloud's announcement</a> for the full details.</p>
<h2 id="built-on-our-reseller-api">Built on our reseller API <a href="#built-on-our-reseller-api" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#built-on-our-reseller-api">#</a></h2>
<p>Both integrations are powered by our <a href="/docs/api/reseller">reseller API</a>. It gives partners everything they need to build a seamless experience:</p>
<ul>
<li><strong>Team provisioning</strong>: create and manage separate client teams programmatically</li>
<li><strong>User management</strong>: add users with roles (admin, member, guest) to each team</li>
<li><strong>Secure login links</strong>: generate time-limited login links so customers can access the full Oh Dear dashboard without creating separate credentials</li>
<li><strong>Monitor management</strong>: create, configure, and manage monitors across all client teams through the standard monitors API</li>
</ul>
<p>The beauty is in the flexibility. Zone gives their customers direct access to the Oh Dear dashboard through login links, so users can configure their own <a href="/features/notifications">notification preferences</a>. Ploi keeps everything inside their own platform and uses <a href="/docs/tools-and-sdks/webhooks">webhooks</a> to feed alerts into their existing notification channels. Both approaches work, both are valid. You tailor it to what fits your product best.</p>
<h2 id="more-to-come">More to come <a href="#more-to-come" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#more-to-come">#</a></h2>
<p>Zone and Ploi Cloud are the first two reseller partners we can publicly share, but there are more in the making. We'll announce them as they go live.</p>
<p>If you run a hosting company, a deployment platform, or a service where website monitoring would be a natural fit for your customers, we'd love to talk. Reach out at <strong><a href="mailto:support@ohdear.app">support@ohdear.app</a></strong> and we'll walk you through the program.</p>
]]>
            </summary>
                                    <updated>2026-06-12T08:58:01+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[5 tips for managing client sites with Oh Dear]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/5-tips-for-managing-client-sites-with-oh-dear" />
            <id>https://ohdear.app/139</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>Managing dozens (or hundreds) of client sites can quickly become chaotic without the right tools. Whether you're running an agency, internal platform team or dev shop, visibility and control are everything. That's where Oh Dear comes in.</p>
<p>Oh Dear is an all-in-one monitoring service that gives you a unified dashboard for uptime checks, performance monitoring, broken link detection, SSL and domain expiry alerts, scheduled task validation and more. But beyond just running checks Oh Dear also gives you powerful tools for organizing and automating how you manage your client sites at scale.</p>
<p>Here are 5 practical ways to make that happen.</p>
<hr />
<h2 id="1-use-tags-to-organize-and-notify">1. Use Tags to Organize and Notify <a href="#1-use-tags-to-organize-and-notify" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#1-use-tags-to-organize-and-notify">#</a></h2>
<p>When you're managing a fleet of sites, grouping them by client, environment, region or team is essential. Oh Dear lets you apply <strong>tags</strong> in any format but we suggest something like:</p>
<ul>
<li><code>client:spatie</code></li>
<li><code>env:production</code></li>
<li><code>infra:cloudflare</code></li>
<li><code>region:eu-west-1</code></li>
<li><code>project:rebrand</code></li>
</ul>
<p>You are probably already aware that you can route notifications to tags or groups of tags.  Once your tags are set up, you can configure <strong>tag group notifications</strong>. This means when something goes wrong on any site tagged with <code>env:production</code> + <code>client:*</code> for example, you can notify a VIP Slack channel or OpsGenie team automatically - no manual routing needed while <code>env:staging</code> + <code>internal</code> can go to the email inbox that no one reads.</p>
<p>See it in practice: <a href="/news-and-updates/why-full-service-agency-marbles-choose-oh-dear-for-its-uptime-monitoring">how full-service agency Marbles uses Oh Dear</a>.</p>
<p>Tags also make onboarding easy. New production application for a <code>client</code>? Just tag it accordingly <code>client:spatie</code> and all the right checks and notifications apply.</p>
<hr />
<h2 id="2-find-sites-by-tag-via-global-search">2. Find Sites by Tag via Global Search <a href="#2-find-sites-by-tag-via-global-search" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#2-find-sites-by-tag-via-global-search">#</a></h2>
<p>Tags aren't just for routing notifications - they’re fully searchable. Open the global search menu in Oh Dear and type any tag (like <code>region:eu-west-1</code> or <code>team:seo</code>) to instantly filter your sites.</p>
<p>This is especially handy for large accounts where you need to quickly check in on just the production sites in Europe or just the ones belonging to a specific customer.</p>
<hr />
<h2 id="3-trigger-health-checks-on-deployment-via-the-api">3. Trigger Health Checks on Deployment via the API <a href="#3-trigger-health-checks-on-deployment-via-the-api" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#3-trigger-health-checks-on-deployment-via-the-api">#</a></h2>
<p>Oh Dear provides an API endpoint to <strong>trigger checks manually</strong>, which is perfect for CI/CD workflows.</p>
<p>This ensures you catch issues <em>before</em> the client does, and keeps your deployment pipeline tightly integrated with live monitoring. Here's how to request a new run of any check, for example the broken links check: https://ohdear.app/docs/api/checks#request-a-run</p>
<p>But you can also apply the same principles to all of our other checks. My favourites are:</p>
<ul>
<li>Lighthouse</li>
<li>Sitemap</li>
</ul>
<pre data-lang="js" class="notranslate"><span class="hl-keyword">const</span> OHDEAR_TOKEN = <span class="hl-value">'your API token'</span>;

<span class="hl-comment">// you can find this via the /sites/{id} endpoint</span>
<span class="hl-comment">// or from the check settings in the app</span>
<span class="hl-keyword">const</span> checkId = 1; 

<span class="hl-property">fetch</span>(<span class="hl-value">'https://ohdear.app/api/checks/1/request-run'</span>, {
  <span class="hl-property">method</span>: <span class="hl-value">'POST'</span>,
  <span class="hl-property">headers</span>: {
    <span class="hl-value">'Authorization'</span>: `Bearer ${OHDEAR_TOKEN}`,
    <span class="hl-value">'Accept'</span>: <span class="hl-value">'application/json'</span>,
    <span class="hl-value">'Content-Type'</span>: <span class="hl-value">'application/json'</span>
  }
})
  .<span class="hl-property">then</span>(res =&gt; {
    <span class="hl-keyword">if</span> (!res.<span class="hl-property">ok</span>) <span class="hl-keyword">throw</span> <span class="hl-keyword">new</span> <span class="hl-type">Error</span>(`HTTP ${res.<span class="hl-property">status</span>}: ${res.<span class="hl-property">statusText</span>}`);
    <span class="hl-keyword">return</span> res.<span class="hl-property">json</span>();
  })
  .<span class="hl-property">then</span>(data =&gt; console.<span class="hl-property">log</span>(<span class="hl-value">'Check run requested:'</span>, data))
  .<span class="hl-property">catch</span>(err =&gt; console.<span class="hl-property">error</span>(<span class="hl-value">'Error triggering check:'</span>, err));
</pre>
<p>Our uptime checks and application health checks run every minute - so that's two extra things we don't have to worry about.</p>
<p>You could also add a maintenance window if you don't have zero-downtime deployments or you are expecting some temporary latency after go-live. Read more here: https://ohdear.app/docs/features/how-to-configure-maintenance-windows</p>
<hr />
<h2 id="4-automate-site-creation-using-templates">4. Automate Site Creation Using Templates <a href="#4-automate-site-creation-using-templates" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#4-automate-site-creation-using-templates">#</a></h2>
<p>When spinning up new client sites speed and consistency is key. Rather than configuring everything from scratch, you can:</p>
<ul>
<li>Assign one of your sites as a <strong>template site</strong> using tag: <code>template</code> with your base checks, tags and settings.</li>
<li>Use the API to <strong>clone</strong> that site when onboarding a new client.</li>
<li>We support all site settings from our API so you can customize the new site as needed (e.g. domain name, team assignments) at the same time.</li>
<li>Add the site to an internal status page and client-facing status page both with custom domains. (Yes you can have as many status pages, custom domains and sites as you need. Included in every plan!)</li>
</ul>
<p>This approach saves time, ensures consistency across all clients and reduces configuration drift.</p>
<p>You are in good company. Oh Dear is the preferred tool for Dutch education and research.</p>
<hr />
<h2 id="5-control-access-with-fine-grained-permissions">5. Control Access with Fine-Grained Permissions <a href="#5-control-access-with-fine-grained-permissions" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#5-control-access-with-fine-grained-permissions">#</a></h2>
<p>Not every stakeholder needs to see everything. Oh Dear lets you <strong>invite clients or teammates</strong> with scoped access:</p>
<ul>
<li>Give dev teams access to performance and scheduled task checks.</li>
<li>Let clients see uptime and SSL status only.</li>
<li>Prevent accidental edits to monitoring settings.</li>
</ul>
<p>This keeps your workspace clean and secure while still being transparent with stakeholders.</p>
<p>You can also add clients to the monthly site reports so they will automatically be up to date. We run reports on the first day of every month.</p>
<p>Tip: client email address can be added to the monthly site report via sites API.</p>
<hr />
<h2 id="bonus-add-site-status-badges">Bonus: Add Site Status Badges <a href="#bonus-add-site-status-badges" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#bonus-add-site-status-badges">#</a></h2>
<p>Want to show the latest status on your client sites? Oh Dear provides a <strong>site badge</strong> you can embed showing current uptime status.</p>
<pre data-lang="js" class="notranslate">
<span class="hl-comment">// https://ohdear.app/api/sites/{id}</span>

{
   ...
   <span class="hl-value">&quot;badge_id&quot;</span>: <span class="hl-value">&quot;01jeb77smcek1f4dxys08vect5&quot;</span>,
   ...
}

</pre>
<p>Then update your content with:</p>
<pre data-lang="html" class="notranslate">&lt;<span class="hl-keyword">img</span> <span class="hl-property">src</span>=&quot;https://ohdear.app/badges/site/{badge_id}/uptime/normal&quot; <span class="hl-property">alt</span>=&quot;uptime status badge&quot; /&gt;
</pre>
<p>It's a small touch that builds trust with clients and surfaces real-time updates to visitors.</p>
<hr />
<h2 id="whats-next">What's Next? <a href="#whats-next" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#whats-next">#</a></h2>
<p>In the next few blog posts, we'll dive deeper into each of these tips with hands-on code examples using the Oh Dear API, tips for setting up automation and ideas for streamlining your agency workflows even further.</p>
<p>Stay tuned!</p>
]]>
            </summary>
                                    <updated>2026-10-16T14:17:07+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[Here are 10 ways to prevent website downtime]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/here-are-10-ways-to-prevent-website-downtime" />
            <id>https://ohdear.app/137</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>Every minute of website downtime cost large organizations <a href="https://www.forbes.com/councils/forbestechcouncil/2024/04/10/the-true-cost-of-downtime-and-how-to-avoid-it/">an average of $9,000</a>. That’s half a million dollars every hour, damn. And that’s just the average. If your organization heavily relies on your website to do business, that cost can increase even further. Needless to say, preventing website downtime is a top priority.</p>
<h2 id="leading-causes-of-website-downtime">Leading causes of website downtime <a href="#leading-causes-of-website-downtime" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#leading-causes-of-website-downtime">#</a></h2>
<p>Before we jump into ways of preventing website downtime, let’s first cover the leading causes of website downtime. If you can diagnose the cause of the downtime, you’ll be in a much better spot to prevent it from happening again. You don't want the perpetual Whac-a-Mole. So, here are the eight leading causes of website downtime:</p>
<ul>
<li><strong>Server issues:</strong> Whether you run your own website servers or pay for third-party hosting, hardware or software issues with your website’s servers can cause your site to go down.</li>
<li><strong>Overwhelmed resources:</strong> A sudden spike in traffic to your website can cause your servers to become overwhelmed preventing additional traffic from accessing your site.</li>
<li><strong>Expired SSL certificates:</strong> Although this doesn’t cause your website to go down, an expired SSL certificate should be treated the same. Most users will navigate away from your site if they receive a warning saying your site is insecure which occurs with an expired SSL certificate.</li>
<li><strong>DNS configuration issues:</strong> Your DNS needs to be configured correctly so that users are directed to your site when they navigate to your site’s URL. A DNS issue prevents people from accessing your site through your domain name.</li>
<li><strong>Software conflicts:</strong> Most sites use software to handle the backend of their website. Any errors with the software, which can occur after an update or due to conflicts between multiple software running different parts of a site’s backend, can cause your site to go down.</li>
<li><strong>Cyberattacks:</strong> Malicious actors can bring your website down with cyberattacks such as <a href="https://www.sciencedirect.com/topics/computer-science/distributed-denial-of-service">DDoS attacks</a> which artificially overwhelm your hosting infrastructure.</li>
<li><strong>Human error:</strong> Mistakes happen more often than we think. Thankfully, if it was human error that took down your website, it usually means you can get it back up by reverting the action that caused the downtime.</li>
<li><strong>Maintenance gone awry:</strong> During scheduled maintenance, things can go wrong that cause the downtime to extend beyond the planned maintenance time.</li>
</ul>
<h2 id="10-ways-to-help-you-to-prevent-website-downtime">10 ways to help you to prevent website downtime <a href="#10-ways-to-help-you-to-prevent-website-downtime" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#10-ways-to-help-you-to-prevent-website-downtime">#</a></h2>
<p>So, how do you prevent those eight leading causes of website downtime from occurring? We’re going to cover the 10 most effective strategies to prevent website downtime and minimize its impact.</p>
<h3 id="implement-global-uptime-monitoring">Implement global uptime monitoring</h3>
<p>To prevent website downtime, you first need to <a href="/uptime-statistics">know when it happens</a>. That can help you identify issues causing your website to go down. It also allows you to take immediate action to bring your site back up when it goes down.</p>
<p>If you are new to this, start with <a href="/news-and-updates/how-does-website-monitoring-even-work">how website monitoring actually works</a>.</p>
<h3 id="monitor-your-ssl-certificates">Monitor your SSL certificates</h3>
<p>Like we mentioned, issues with your SSL certificate won’t cause website downtime, but it does divert traffic. When issues with your SSL certificate exist, anyone navigating to your website will be greeted with a big warning from their browser saying your site is not secure. Most people do not choose to proceed to your site after that warning. SSL certificate monitoring ensures you’re the first person to know about any issues with your certificate so you can fix it before they impact your users.</p>
<h3 id="set-up-performance-monitoring">Set up performance Monitoring</h3>
<p>Pages that load slowly can have just as big of an impact as a page being down. When a page takes over three seconds to load, nearly half of users will leave your site. Performance monitoring keeps an eye on how long it takes your site to load and tells you what’s bogging down your load times. That gives you the information you need to make your site faster.</p>
<h3 id="implement-dns-monitoring">Implement DNS monitoring</h3>
<p>Internal tests can easily miss DNS errors. Afterall, an issue with your DNS won’t prevent your server from sending data to a test environment. But, it does prevent your users from accessing your website. You need your DNS configured correctly to ensure your users can access your site through your domain name. DNS monitoring checks your configuration, ensures users can access your domain, and tells you where the error exists if there is an issue with your DNS records.</p>
<h3 id="schedule-regular-backups">Schedule regular backups</h3>
<p>Downtime is not 100% avoidable. There will be errors that happen whether they’re human errors, an issue with your hosting servers, or a software issue. Scheduling regular backups allows you to rollback your changes at any time while minimizing progress loss. This can immediately bring your website back up if you run into software issues or a human error that takes down your site.</p>
<h3 id="implement-load-balancing">Implement load balancing</h3>
<p>Without load balancing, a single server becoming overwhelmed can prevent some users from accessing your website. Load balancing spreads out the traffic to your website between multiple servers preventing any one server from becoming overwhelmed. This makes your website more scalable as you can add more servers to accommodate increases in traffic.</p>
<h3 id="monitor-scheduled-tasks">Monitor scheduled tasks</h3>
<p>Whether its database or server maintenance, keep track of scheduled tasks and monitor their progress. These tasks can fail and if not monitored, can cause cascading effects that create downtime for your website.</p>
<h3 id="check-for-mixed-content">Check for mixed content</h3>
<p>Mixed content doesn't cause downtime, but it does create a poor user experience. Browsers can identify mixed content and then send users a security warning just like with SSL certificate issues. Monitoring for this type of content tells you what pages it affects so that you can fix it.</p>
<h3 id="set-up-application-health-monitoring">Set Up application health monitoring</h3>
<p>Most modern websites use various applications to run all the aspects of their site. These applications need to work in tandem for every part of your site to work. Application health monitoring notifies you of issues within an application and with the integration of each application so that it can work cohesively.</p>
<h3 id="create-and-maintain-a-status-page">Create and maintain a status page</h3>
<p>When downtime occurs, communication is critical. You want your users to know that your website will be coming back up and, if you can, give them a timeframe of when they can expect your site to be back up. So, create and maintain a status page with all relevant information you can display during downtime.</p>
<h2 id="monitoring-your-website">Monitoring your website <a href="#monitoring-your-website" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#monitoring-your-website">#</a></h2>
<p>One more: do not forget your cron jobs, <a href="/features/scheduled-task-monitoring">scheduled task monitoring</a> covers those.</p>
<p>It can sound overwhelming to manage all this stuff just to prevent downtime and fix issues before they impact your users. But guess what, modern website monitoring solutions—like <a href="https://ohdear.app/register">Oh Dear</a> of course—can manage all of the above with minimal effort from your end. They offer you a single dashboard to track all relevant aspects of your website from your performance and uptime to your SSL certificate and DNS records. You can try OhDear for free for 10 days to see how website monitoring can help you better manage your sites.</p>
<h2 id="faqs-about-website-downtime">FAQs about website downtime <a href="#faqs-about-website-downtime" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#faqs-about-website-downtime">#</a></h2>
<p><strong>How can I quickly respond to website downtime?</strong>
Website monitoring is the best way to get notified of website downtime immediately so that you can respond to it as quickly as possible.</p>
<p><strong>Should I notify users about downtime?</strong>
Yes, proactive communication is the best way to minimize the impacts of downtime to your end user. Be open about the cause of the downtime, how long you expect it to impact users, and the extent of the impact.</p>
<p><strong>How do I diagnose the cause of website downtime?</strong>
You can start your diagnosis with the monitoring tool that notified you of the downtime. It should tell you the general cause of the error based on the HTTP status code the monitoring service received to identify the downtime. From there, you need to systematically test ever aspect related to the general cause until you find the point of failure.</p>
<p><strong>What should I include in my website downtime status page?</strong>
When displaying a status page notifying users that your website is currently down, we recommend including information related to when they can expect your website to come back up as well as a sign-up form that allows users to receive a notification when your website is back up.</p>
]]>
            </summary>
                                    <updated>2026-10-16T14:17:07+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[How does website monitoring even work?]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/how-does-website-monitoring-even-work" />
            <id>https://ohdear.app/134</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>Every website manager knows that feeling when you look at your inbox only to find a customer notifying you that a core page of your site is down. The worst part of it all, you don’t know how long that page has been down for. If you’ve yet to experience that, count your blessings. Well, unless you decide to opt for a website monitoring solution before it happens to you.</p>
<p>With website monitoring, you can ensure every page on your site is up and running at all times. And if any of them go down, you’ll be the first person to know. That way, you can fix the problem before it impacts any of your customers.</p>
<h2 id="the-technical-process-of-website-monitoring">The technical process of website monitoring <a href="#the-technical-process-of-website-monitoring" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#the-technical-process-of-website-monitoring">#</a></h2>
<p>Obviously, website monitoring monitors your website. But, how does that process actually work? It’s simpler than it sounds. Basically, the software uses an automated system to regularly check every page on your website and ensure an end-user could access them.</p>
<h3 id="the-request-response-cycle">The request-response cycle</h3>
<p>Let’s dig into the details of how that automated system works. It continuously sends your website server HTTP requests triggering the server to send an HTTP response back. That HTTP response includes a status code telling the monitoring service the current status of the page. Those HTTP status codes include:</p>
<ul>
<li><strong>HTTP 2xx:</strong> A response with a HTTP status code in the 200s is the expected response. It means the page is up and running.</li>
<li><strong>HTTP 3xx:</strong> This means the page is redirecting traffic to a different page. This could be expected, but not always.</li>
<li><strong>HTTP 4xx:</strong> When there’s a problem with the code in one of your pages that prevents it from being displayed.</li>
<li><strong>HTTP 5xx:</strong> When your server cannot fulfil an HTTP request, like an issue with your website host or servers.</li>
</ul>
<p>Receiving the status code for every page on your site is the basics of website monitoring. These services can do a lot more, though. For instance, they can also track how long it takes to fulfil a request so you can monitor the performance of your website.</p>
<p>That way, you can tell if a large uptick in traffic slows down your website which could mean you need to invest in faster server infrastructure.</p>
<p>You can even <a href="/docs/api/checks#request-a-run">trigger an on-demand check right after a deploy</a>.</p>
<h2 id="types-of-website-monitoring">Types of website monitoring <a href="#types-of-website-monitoring" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#types-of-website-monitoring">#</a></h2>
<p>The specialty tasks website monitoring can perform, like the performance testing we just mentioned, depends on the type of website monitoring provided. Here are the main types of website monitoring you should look for when signing up for a website monitoring service:</p>
<h3 id="uptime-monitoring">Uptime monitoring</h3>
<p>This is the main type of website monitoring. It uses the process we discussed earlier with making an HTTP request and then analyzing the response code. However, more advanced uptime monitoring doesn’t just check that your website is up, it can also check for specific features in your website. Other services allow you to check that your website is up in specific regions or globally by making requests from localized servers.</p>
<p>It is not just GET, you can <a href="/docs/features/uptime-and-performance-monitoring">monitor POST, PUT and PATCH endpoints</a> too.</p>
<h3 id="ssl-certificate-monitoring">SSL certificate monitoring</h3>
<p>We’ve all gone to a site and saw the “your connection is not private” warning. That’s what happens when a site has an SSL certificate error. And just like you, that warning turns traffic away immediately. So, while receiving an HTTP response code, quality monitoring services also check the status of your SSL certificate and notify you of any errors. That way, you can fix any issues before your visitors notice them.</p>
<h3 id="broken-link-detection">Broken link detection</h3>
<p>Every website uses internal links and if you don’t, you should. But when you delete a page, it’s hard to find every single time you linked to that page on other pages. Or, if you change the URL of a page, finding every instance of a link to that URL can be a challenge. Broken link detection finds these issues for you while scouring your website. The service goes through each link on the page and makes sure it returns a valid HTTP response code as well.</p>
<h3 id="mixed-content-warnings">Mixed content warnings</h3>
<p>Just like an error with your SSL certificate can send your visitors a warning, mixed content on your pages does that too. That’s when your page has an SSL certificate and uses HTTPS, but content within your page uses insecure HTTP resources. This can cause your visitors to go running just like with an SSL certificate error. Monitoring this requires your website monitoring service to load all resources on the page and assess each one’s security status.</p>
<h3 id="performance-monitoring">Performance monitoring</h3>
<p>It’s easy to tell how quickly a website responds, but the information performance monitoring services can tell you a lot more than just how long it takes for a page to load from the time you enter the URL. It breaks down your page loading time into separate categories so you can identify the bottlenecks impeding your website’s performance.</p>
<p>Beyond up or down, we also watch speed, see <a href="/features/performance-monitoring">performance monitoring</a>.</p>
<h3 id="domain-monitoring">Domain monitoring</h3>
<p>There’s a lot that can go wrong with a domain. Whether it’s about to expire or someone fraudulently updated the WHOIS records, keeping tabs on your domain is just as important as keeping tabs on your website’s performance. That’s why most website monitoring services monitor your domain as well. They look for unexpected activity, warn you when your domain is about to expire, and verify all of your email-related records.</p>
<h2 id="what-kind-of-website-monitoring-do-you-need">What kind of website monitoring do you need? <a href="#what-kind-of-website-monitoring-do-you-need" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-kind-of-website-monitoring-do-you-need">#</a></h2>
<p>Clearly there's no shortage in different types of website monitoring, but in practice you usually don’t need to pick and choose. Tools like UptimeRobot, StatusCake, and <a href="https://ohdear.app/register">Oh Dear</a> are considered &quot;all-in-one&quot; monitoring solutions. All types of monitoring are included, coupled with a robust notification system. What's also cool and totally not self-promotional, is that Oh Dear offers unlimited status pages, Lighthouse SEO monitoring and broken links and content detection as well! I know what I'd choose!</p>
<p><img src="/media/blog/CPgVriz7TRT55j76AV8GyXLfqka5qIZtHWMkZmnD.png" alt="A banner promoting Oh Dear as an all-in-one website monitoring tool" /></p>
]]>
            </summary>
                                    <updated>2026-10-16T14:17:09+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[Status Page Templates: Incident & Maintenance Examples You Can Copy]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/new-feature-status-page-update-templates" />
            <id>https://ohdear.app/120</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>We know how crucial it is to provide clear and timely communication during incidents or downtime. That’s why we’re excited to introduce Status Page Update Templates - a new feature that makes it even easier to keep your users informed while maintaining a consistent message.</p>
<h2 id="status-page-templates-you-can-copy">Status page templates you can copy <a href="#status-page-templates-you-can-copy" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#status-page-templates-you-can-copy">#</a></h2>
<p>When something breaks, nobody wants to stare at an empty text box. Copy the update that fits, fill in the [brackets], and post it on your <a href="/features/status-pages">status page</a>. Each one lists the severity to pick in Oh Dear.</p>
<p>Keep posting while it's broken, every 30 minutes or so, even when nothing changed. Silence makes people assume the worst.</p>
<h3 id="incident-investigating">Incident: investigating</h3>
<p>Severity: <strong>High</strong></p>
<blockquote>
<p><strong>Investigating issues with [service]</strong></p>
<p>We're looking into reports of [errors / slow pages / failed logins] on [service], starting at [time] UTC. You might not be able to [action] right now. We'll post an update within 30 minutes, sooner if we find the cause.</p>
</blockquote>
<h3 id="incident-cause-identified">Incident: cause identified</h3>
<p>Severity: <strong>High</strong></p>
<blockquote>
<p><strong>Cause found, fix in progress</strong></p>
<p>We've found the cause: [short, plain description, e.g. a failed database update]. We're rolling out a fix now. [Service] stays [unavailable / slow] until it's live. Next update within 30 minutes.</p>
</blockquote>
<h3 id="incident-monitoring-the-fix">Incident: monitoring the fix</h3>
<p>Severity: <strong>Warning</strong></p>
<blockquote>
<p><strong>Fix deployed, monitoring</strong></p>
<p>The fix is live and [service] is working again for most of you. We're keeping an eye on it to make sure it stays that way. Still seeing [problem]? Try [refreshing / logging in again] or contact [support address].</p>
</blockquote>
<h3 id="incident-resolved">Incident: resolved</h3>
<p>Severity: <strong>Resolved</strong></p>
<blockquote>
<p><strong>Resolved: [service] is back to normal</strong></p>
<p>[Service] has been working normally since [time] UTC. Between [start time] and [end time], [what people saw, e.g. the dashboard didn't load]. The cause was [cause]. We've [what you changed] so it doesn't happen again. Sorry for the trouble, and thanks for your patience.</p>
</blockquote>
<h3 id="maintenance-scheduled">Maintenance: scheduled</h3>
<p>Severity: <strong>Scheduled maintenance</strong></p>
<blockquote>
<p><strong>Scheduled maintenance on [date]</strong></p>
<p>On [date] from [start time] to [end time] UTC, we're [upgrading our database / moving to new servers]. During that window, [service] will be [unavailable / read-only / slower than usual]. You don't need to do anything. We'll post here when we start and when we're done.</p>
</blockquote>
<h3 id="maintenance-in-progress">Maintenance: in progress</h3>
<p>Severity: <strong>Scheduled maintenance</strong></p>
<blockquote>
<p><strong>Maintenance in progress</strong></p>
<p>Our scheduled maintenance has started. [Service] is [unavailable / read-only] until about [end time] UTC. We'll update this page when we're done.</p>
</blockquote>
<h3 id="maintenance-completed">Maintenance: completed</h3>
<p>Severity: <strong>Resolved</strong></p>
<blockquote>
<p><strong>Maintenance completed</strong></p>
<p>Maintenance finished at [time] UTC and [service] is fully available again. If anything looks off, contact [support address].</p>
</blockquote>
<p>Want these one click away next time? Save them as templates in Oh Dear, here's how.</p>
<h2 id="why-use-a-status-page">Why use a status page <a href="#why-use-a-status-page" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#why-use-a-status-page">#</a></h2>
<p>A <a href="/features/status-pages">status page</a> is a dedicated, Oh Dear hosted site where you can communicate the current status of your website or service to your users by posting status updates. It's a simple yet powerful tool for transparency and trust-building. Here’s why you should consider having one.</p>
<ul>
<li><strong>Keep Users Informed</strong>: Communicate issues, such as downtime, slow performance, or scheduled maintenance, directly to your users. Instead of leaving them guessing or frustrated, they’ll know exactly what’s going on.</li>
<li><strong>Reduce Support Overhead</strong>: Proactively provide information and reduce the number of support tickets when issues arise.</li>
<li><strong>Build Trust</strong>: Transparency is key. Being open about issues builds trust with your users - a status page demonstrates that you are committed to keeping them in the loop.</li>
<li><strong>Improve User Experience</strong>: Users are more understanding of problems when they know what's happening and what to expect. By managing expectations you show that you’re on top of the situation.</li>
<li><strong>Centralised Communication</strong>: During an incident, a status page acts as a single source of truth, where all updates are published in real time. This ensures consistent messaging across all your communication channels.</li>
</ul>
<h2 id="why-use-status-page-update-templates">Why Use Status Page Update Templates? <a href="#why-use-status-page-update-templates" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#why-use-status-page-update-templates">#</a></h2>
<p>Things go wrong. While there is pressure to resolve the issue, there is also pressure to communicate quickly and accurately. With our new templates, you can:</p>
<ul>
<li><strong>Ensure Consistent Messaging</strong>: Keep your communications clear and consistent, reducing confusion for your users.</li>
<li><strong>Save Time During High-Pressure Situations</strong>: Apply a pre-made template, fill in the specifics, and publish your update in moments.</li>
<li><strong>Reduce Stress</strong>: No need to worry about drafting the perfect message; simply use a template and modify placeholders as needed.</li>
</ul>
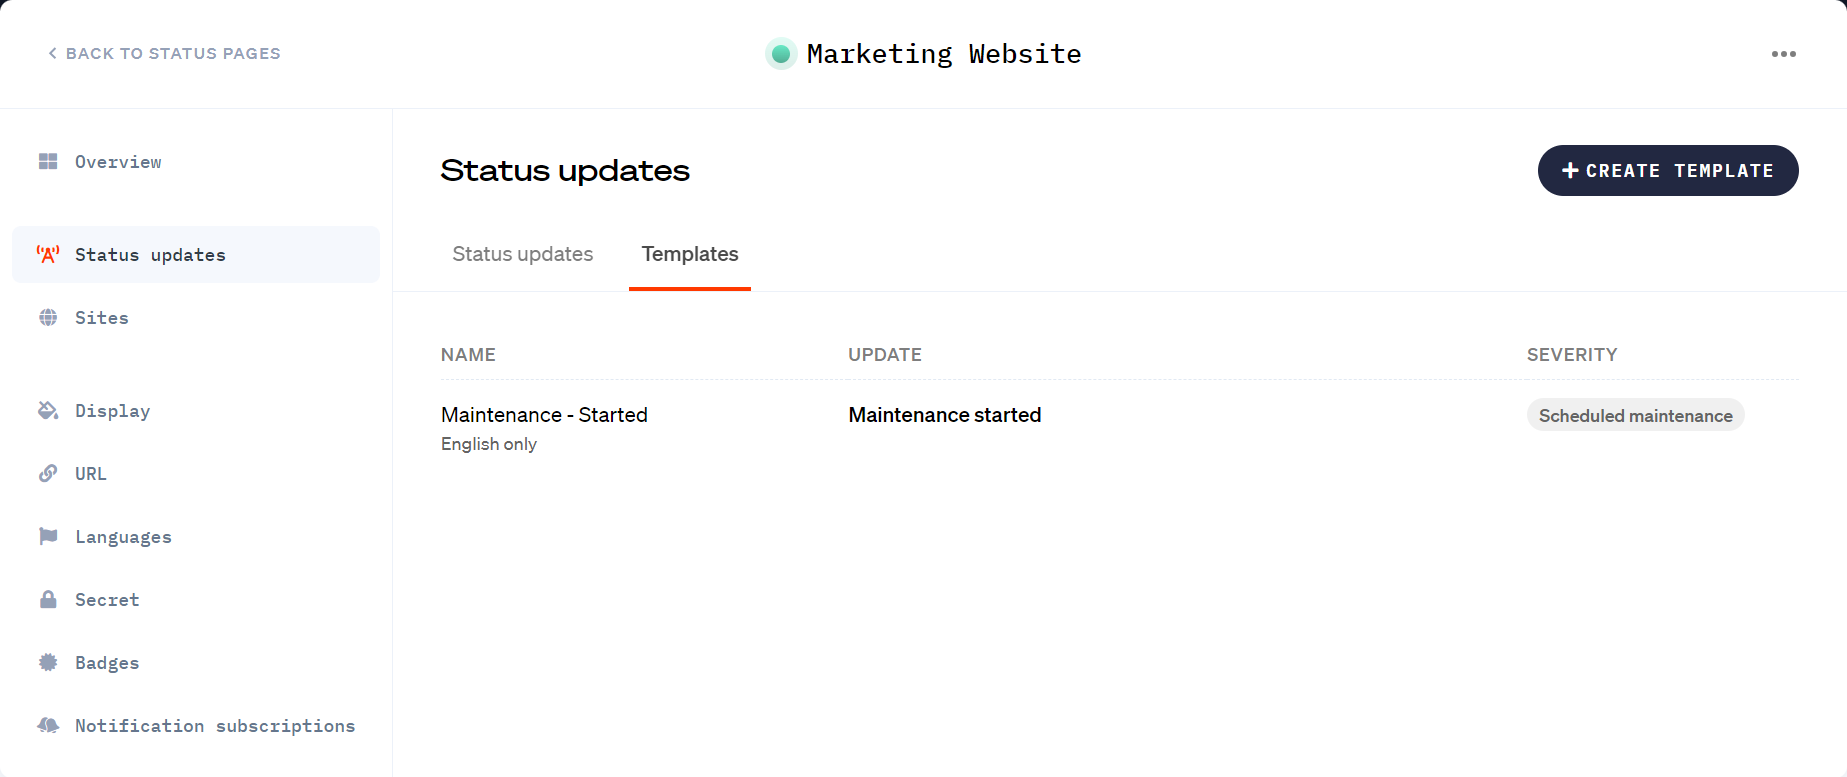
<p><img src="/media/blog/O2KpXX9eDO07BRcEM8l9sh7o0naPqcZC1n9iVIyZ.png" alt="Status page templates tab listing a Maintenance - Started update template with scheduled maintenance severity" /></p>
<h2 id="key-features">Key Features <a href="#key-features" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#key-features">#</a></h2>
<p>Here’s why we think Status Page Update Templates are awesome.</p>
<ul>
<li><strong>Named Templates</strong>: Create templates that are easy to find and apply.</li>
<li><strong>Flexible Fields</strong>: Not all fields are required—you can save a template with just a description or any other combination that suits your needs.</li>
<li><strong>Quick Apply</strong>: Simply select a template when creating a new update then make any necessary adjustments before publishing.</li>
<li><strong>API Support</strong>: Manage your templates with new API endpoints for listing, creating, updating and deleting templates.</li>
</ul>
<h2 id="create-your-first-template">Create your first template <a href="#create-your-first-template" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#create-your-first-template">#</a></h2>
<p>Getting started with Status Page Update Templates is easy:</p>
<ol>
<li>Go to the 'Status Pages' section in your Oh Dear dashboard menu and select a status page to edit.</li>
<li>Select 'Status updates' in the sidebar.</li>
<li>Select 'Templates' tab.</li>
<li>Select 'Create Template'.</li>
<li>Fill in the name and any title, description, text, and severity level you need to use.</li>
<li>Click 'Save Template'.</li>
</ol>
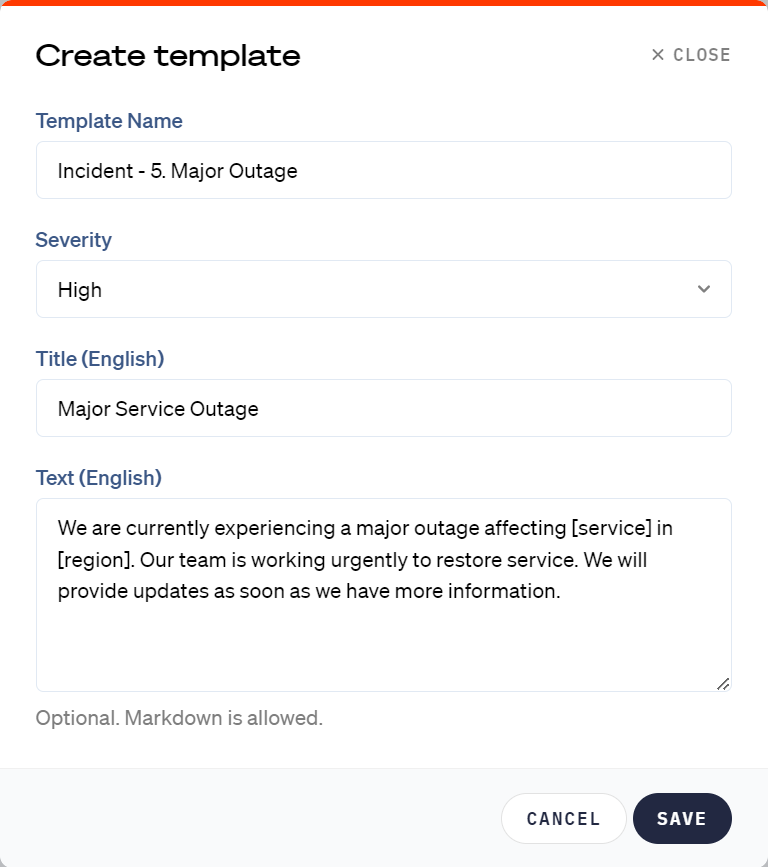
<p>When an incident occurs, you can select a template from the list while creating a status update, and modify any placeholders as needed.</p>
<p><img src="/media/blog/QMGeshDqDwj0P7rKEaOfZZviXmJoXHrNl1m3FXst.png" alt="Create template dialog for a Major Service Outage status update with high severity, title and text fields" /></p>
<h2 id="api">API <a href="#api" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#api">#</a></h2>
<p>If you're looking to automate your status updates, we’ve got you covered! The Oh Dear API now supports managing status page templates with the following endpoints:</p>
<ul>
<li><strong>List Templates</strong>: Fetch all saved templates.</li>
<li><strong>Create Templates</strong>: Add a new template with the desired fields.</li>
<li><strong>Update Templates</strong>: Modify existing templates.</li>
<li><strong>Delete Templates</strong>: Remove templates you no longer need.</li>
</ul>
<p>Read the full <a href="/docs/api/introduction#status-pages">API documentation</a> to help you start managing your template integrations!</p>
<h2 id="a-more-user-friendly-approach">A More User-Friendly Approach <a href="#a-more-user-friendly-approach" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#a-more-user-friendly-approach">#</a></h2>
<p>We believe this new feature will make it easier for you to communicate effectively with your users. Whether you’re a small team managing one site or a large team overseeing multiple domains, having a set of templates ready can make all the difference during critical moments.</p>
]]>
            </summary>
                                    <updated>2026-10-16T14:17:08+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[Let's Encrypt DST Root CA X3 certificate set to expire]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/lets-encrypt-dst-root-ca-x3-certificate-set-to-expire" />
            <id>https://ohdear.app/65</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>If you've been using Let's Encrypt for a while, you may have noticed that their certificates are signed by a root certificate titled <em>DST Root CA X3</em>.</p>
<p>That root certificate is set to expire in a few hours. Any certificates still signed by that root will no longer be valid. But luckily, that shouldn't form a problem for most Let's Encrypt users.</p>
<p>For a while now, new SSL issuances by Let's Encrypt have issued certificates against DST Root CA X3 (the one that is about to expire) <em>and</em> ISRG Root X1. The former will expire, the latter remains valid for years to come.</p>
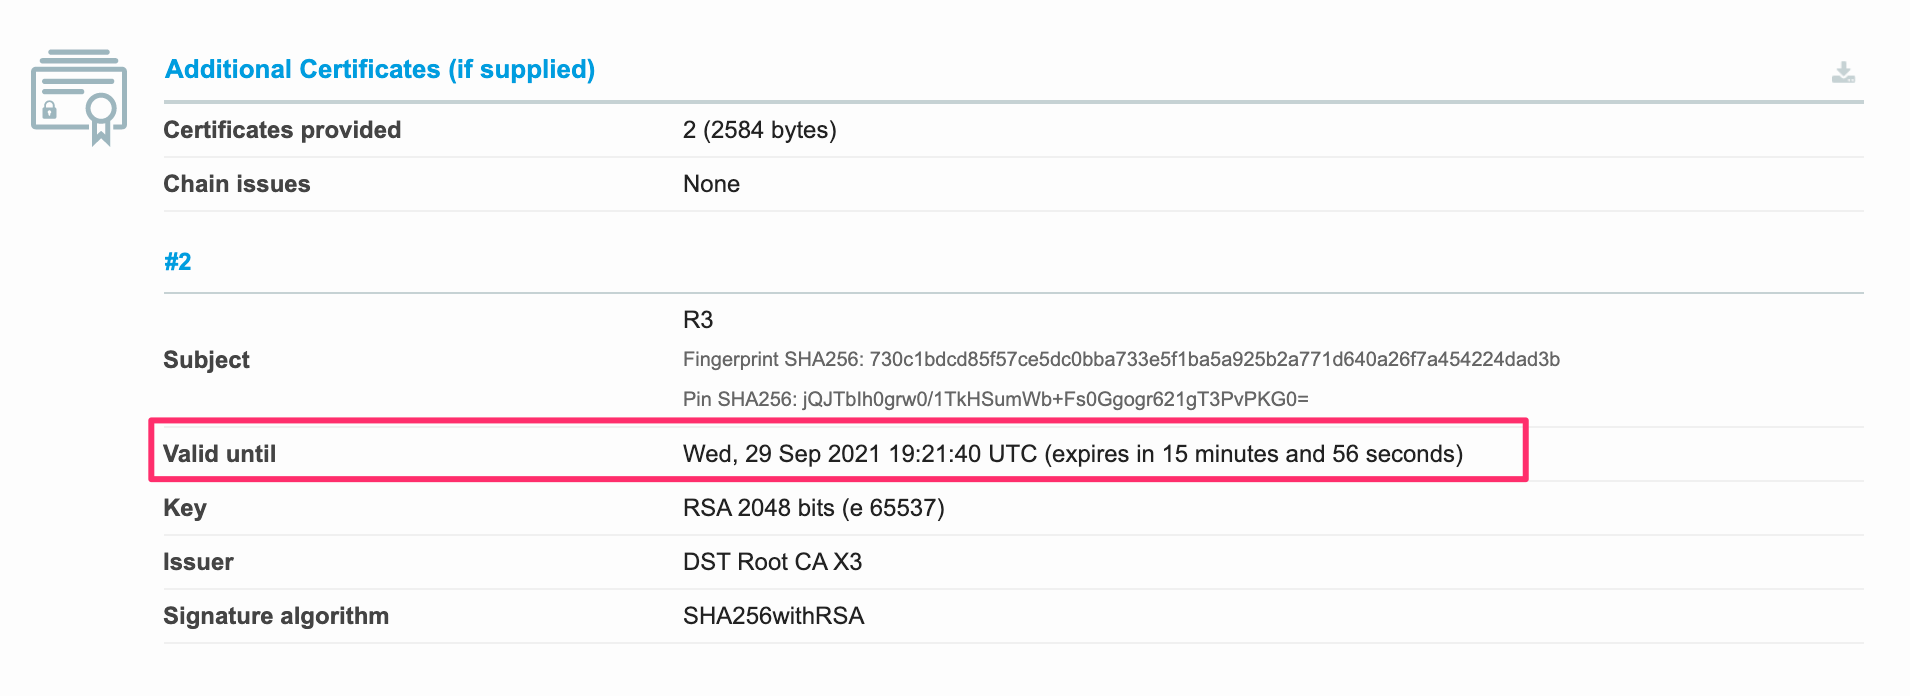
<p>If Oh Dear detects you're sending along the older, about to expire, intermediate certificate in your certificate chain, we'll notify you to take action:</p>
<p><img src="/uploads/blogs/letsencrypt-r3-expires/letsencrypt_r3_expire.png" alt="Lets Encrypt R3 expiration" /></p>
<p>The fix would be to re-issue certificates <em>or</em> manually change the certificate chain in your configuration that you're sending along via your webserver.</p>
<p>While this will only affect much older devices (ie: iPhone 4 or older), we feel it's important we notify our clients should this affect them.</p>
<p>For more details, we kindly refer to the <a href="https://letsencrypt.org/docs/dst-root-ca-x3-expiration-september-2021/">official Let's Encrypt explanation of their expiring root certificate</a>.</p>
]]>
            </summary>
                                    <updated>2021-09-29T19:17:28+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[How Oh Dear identified a certificate problem at a large CDN provider]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/how-oh-dear-identified-a-certificate-problem-at-a-large-cdn-provider" />
            <id>https://ohdear.app/37</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>As part of our service, we perform <a href="/features/continuous-certificate-monitoring">SSL certificate monitoring</a>. We do this slightly different than other providers, which is why were able to detect a problem with the SSL certificates of a large, commercial, CDN provider.</p>
<p>In this post, we'll do a technical deep-dive into how we found this problem!</p>
<h2 id="why-we-found-it-in-the-first-place">Why we found it in the first place <a href="#why-we-found-it-in-the-first-place" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#why-we-found-it-in-the-first-place">#</a></h2>
<p>While we're a traditional website monitoring service in some aspects, we do a couple of things differently from our competition (and I'm not just talking about our crawler that <a href="/features/broken-page-and-mixed-content-detection">looks for broken links &amp; mixed content</a>).</p>
<p>Our SSL monitoring is fairly <em>intense</em>. We fetch and validate the <strikethrough>SSL</strikethrough> <strikethrough>TLS</strikethrough> x.509 certificates <strong>every 30 minutes</strong>, for each site, to report on changes and problems.</p>
<p>With dozens of checks a day for the SSL certificate alone, it means we have a lot of opportunities to catch errors related to your site certificates.</p>
<p>This allows us to quickly identify situations where a certificate has changed (use case: did you renew <em>all</em> the SANs on the certificate?) or one that has incorrectly been replaced.</p>
<h2 id="what-happened-here">What happened here? <a href="#what-happened-here" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-happened-here">#</a></h2>
<p>In this case, we received reports from multiple of our clients that our certificate change reporting <em>&quot;seemed wrong&quot;</em>. We were sending alerts to clients that their certificates had changed, but they could never quite verify this.</p>
<p>When we connect to a host to do our in-depth certificate analysis, we fetch as much information as we can. It's similar to how OpenSSL's client would do it:</p>
<pre data-lang="bash" class="notranslate">$ openssl s_client \
	-connect clientsite.tld:443 \
	-servername clientsite.tld \
	2&gt;/dev/null \
	| <span class="hl-keyword">grep</span> <span class="hl-value">'CN'</span>

 0 s:/CN=clientsite.tld
   i:/C=US/O=Let<span class="hl-value">'s Encrypt/CN=Let'</span>s Encrypt Authority X3
 1 s:/C=US/O=Let<span class="hl-value">'s Encrypt/CN=Let'</span>s Encrypt Authority X3
   i:/O=Digital Signature Trust Co./CN=DST Root CA X3
subject=/CN=clientsite.tld
issuer=/C=US/O=Let<span class="hl-value">'s Encrypt/CN=Let'</span>s Encrypt Authority X3
</pre>
<p>This is what you'd expect: a connection to the host <code>clientsite.tld</code>, where we make clear that we want to retrieve the certificate information using SNI - Server Name Indication.</p>
<p>The above example is a functioning one, it correctly returned us the certificate of the site, and we could verify everything was intact.</p>
<p>However, every once in a while, this happened:</p>
<pre data-lang="bash" class="notranslate">$ openssl s_client \
	-connect clientsite.tld:443 \
	-servername clientsite.tld \
	2&gt;/dev/null \
	| <span class="hl-keyword">grep</span> <span class="hl-value">'CN'</span>

 0 s:/OU=Domain Control Validated/CN=*.cdnprovider.com
   i:/C=US/ST=State/L=Location/O=GoDaddy.com, Inc./OU=http://certs.godaddy.com/repository//CN=Go Daddy Secure Certificate Authority - G2
 1 s:/OU=Domain Control Validated/CN=*.cdnprovider.com
   i:/C=US/ST=State/L=Location/O=GoDaddy.com, Inc./OU=http://certs.godaddy.com/repository//CN=Go Daddy Secure Certificate Authority - G2
 2 s:/C=US/ST=State/L=Location/O=GoDaddy.com, Inc./OU=http://certs.godaddy.com/repository//CN=Go Daddy Secure Certificate Authority - G2
   i:/C=US/ST=State/L=Location/O=GoDaddy.com, Inc./CN=Go Daddy Root Certificate Authority - G2
 3 s:/C=US/ST=State/L=Location/O=GoDaddy.com, Inc./CN=Go Daddy Root Certificate Authority - G2
   i:/C=US/ST=State/L=Location/O=GoDaddy.com, Inc./CN=Go Daddy Root Certificate Authority - G2
ct6W1bEcW10r8Nvp0lZrYmdIn//gn4ltYpiWtRCRROEa81WO5lNDL5NO5gJ1I6CN
subject=/OU=Domain Control Validated/CN=*.cdnprovider.com
</pre>
<p>We requested the certificate for domain <code>clientsite.tld</code> but got back a certificate for <code>*.cdnprovider.com</code>.</p>
<p>Clearly this shouldn't happen!</p>
<p>As a result, our alerts got sent to the client, because their site was being served by an incorrect certificate.</p>
<h2 id="changes-made-at-oh-dear-to-help-verify-this">Changes made at Oh Dear to help verify this <a href="#changes-made-at-oh-dear-to-help-verify-this" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#changes-made-at-oh-dear-to-help-verify-this">#</a></h2>
<p>When we received the first reports, it wasn't easy to troubleshoot this. You see, we connect to the hostname <code>clientsite.tld</code>, but that might be served by several IP addresses using DNS Round Robin.</p>
<pre data-lang="bash" class="notranslate">$  dig +short +noshort clientsite.tld
clientsite.tld.		66	IN	A	1.2.3.4
clientsite.tld.		66	IN	A	5.6.7.8
</pre>
<p>In fact, that's how most CDNs operate: you point your domain to a CNAME, and they present multiple anycasted IPs, each capable of serving your site.</p>
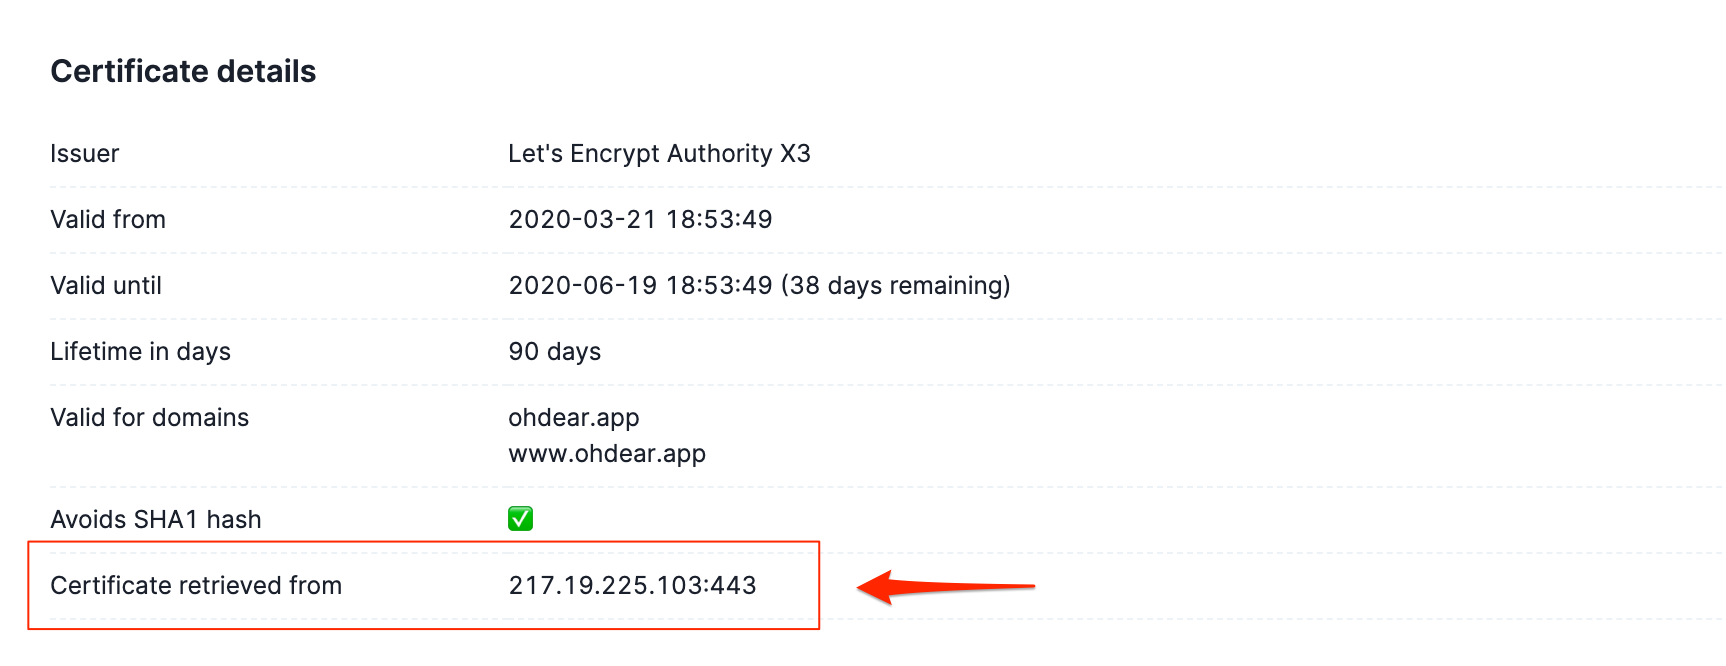
<p>Our problem was that we didn't present the IP that we used for this certificate check back to you, the user. So how could you know which IP served the wrong certificate?</p>
<p>As part of our debugging, we made this available to all users in the detailed view of their certificate report:</p>
<p><img src="/uploads/blogs/cdn-provider-ip-used-in-check/cdn-provider-ip-retrieved-check.png" alt="Certificate retrieved from what IP?" /></p>
<p>To do this, we <a href="https://github.com/spatie/ssl-certificate/commit/3b1798a9ed8b7b598731594d285be5792b6eb00a">contributed to the upstream SSL package</a> to expose the remote address IP, since this wasn't available out of the box.</p>
<pre data-lang="php" class="notranslate"><span class="hl-comment">/* ... */</span>
<span class="hl-variable">$response</span>[<span class="hl-value">'remoteAddress'</span>] = <span class="hl-property">stream_socket_get_name</span>(<span class="hl-variable">$client</span>, <span class="hl-keyword">true</span>);
</pre>
<p>But, this wasn't enough to easily pinpoint the issue.</p>
<h2 id="working-together-with-the-cdn">Working together with the CDN <a href="#working-together-with-the-cdn" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#working-together-with-the-cdn">#</a></h2>
<p>You see, many of the IPs of a CDN are &quot;anycast&quot; IPs: you connect to an IP address, but there might be multiple servers worldwide responding to that very same IP.</p>
<p>The short version is: the one closest to you (in BGP-terms) will provide you the answer. But for the CDN provider, there's no way to uniquely identify which of their thousands of servers actually responded.</p>
<p>We worked together with them to provide all technical details of our checks and sufficient example/test cases to, at first, convince them of this problem. Then, our examples helped them to troubleshoot and resolve the problem on their end.</p>
<blockquote>
<p>I wanted to let you know that we found two edge servers that were mis-behaving and causing the issue you were seeing. We did a full sweep of the thousands of servers we manage and confirmed no others were in this bad state.</p>
<p>-- Director of Customer Support</p>
</blockquote>
<p>We're thrilled to see the widespread implications of our <em>paranoid</em> certificate monitoring, and that, as a result, we helped thousands of sites worldwide. Even those not using Oh Dear!</p>
]]>
            </summary>
                                    <updated>2026-07-13T06:48:51+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[Finding clients hit by Let's Encrypt mass-revocation]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/how-we-identified-clients-with-ssl-certificates-affected-by-lets-encrypt-mass-revocation" />
            <id>https://ohdear.app/30</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>Yesterday, we sent out notifications to all clients whose certificates we <a href="/features/continuous-certificate-monitoring">continuously monitor</a> and that are affected by the <a href="https://community.letsencrypt.org/t/revoking-certain-certificates-on-march-4/114864">Let's Encrypt mass revocation of SSL certificates</a>. In this post, we'll share the details how we found those certificates.</p>
<p>Now, the <em>morning after</em>, we're well rested and in good shape to do a proper write-up on the matter.</p>
<h2 id="getting-a-list-of-all-domains-to-check">Getting a list of all domains to check <a href="#getting-a-list-of-all-domains-to-check" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#getting-a-list-of-all-domains-to-check">#</a></h2>
<p>As part of our <a href="/features/website-uptime-monitoring">uptime monitoring</a>, users can add a site to Oh Dear with specific URL parameters. So in order to get a list of domains we needed to verify, it wasn't as simple as:</p>
<pre data-lang="sql" class="notranslate"><span class="hl-keyword">SELECT</span> <span class="hl-property">domain</span> <span class="hl-keyword">FROM</span> <span class="hl-type">sites</span>;
</pre>
<p>Instead, we used Laravel's lazy collections to quickly filter all teams with active subscriptions and extract the relevant domain name.</p>
<pre data-lang="php" class="notranslate"><span class="hl-type">Team</span>::<span class="hl-property">cursor</span>()
    -&gt;<span class="hl-property">filter</span>(<span class="hl-keyword">fn</span> (<span class="hl-injection"><span class="hl-type">Team</span> $team</span>) =&gt; <span class="hl-variable">$team</span>-&gt;<span class="hl-property">hasActiveSubscriptionOrIsOnGenericTrial</span>())
    -&gt;<span class="hl-property">flatMap</span>(<span class="hl-keyword">fn</span> (<span class="hl-injection"><span class="hl-type">Team</span> $team</span>) =&gt; <span class="hl-variable">$team</span>-&gt;<span class="hl-property">sites</span>)
    -&gt;<span class="hl-property">map</span>(<span class="hl-keyword">fn</span> (<span class="hl-injection"><span class="hl-type">Site</span> $site</span>) =&gt; <span class="hl-variable">$site</span>-&gt;<span class="hl-property">domain</span>())
    -&gt;<span class="hl-property">each</span>(<span class="hl-keyword">fn</span> (<span class="hl-injection"><span class="hl-type">string</span> $output</span>) =&gt; <span class="hl-keyword">echo</span> <span class="hl-variable">$output</span> . <span class="hl-property">PHP_EOL</span>);
</pre>
<p>This produced a new-line separated list of domains that we need to check.</p>
<p>Let's save those in <code>domains.txt</code>, since we're moving to some CLI tricks now.</p>
<h2 id="retrieving-the-serial-for-each-certificate">Retrieving the serial for each certificate <a href="#retrieving-the-serial-for-each-certificate" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#retrieving-the-serial-for-each-certificate">#</a></h2>
<p>Now we find the active <em>Serial Number</em> for each of those certificates. It involves connecting to each site over SSL/TLS, getting the certificate and saving the <em>Serial Number</em>.</p>
<p>The original idea came from <a href="https://news.ycombinator.com/item?id=22475943">a Hacker News comment</a>, we modified it to get some better error handling and control of the output.</p>
<pre data-lang="bash" class="notranslate"><span class="hl-comment"># Create a directory to hold all serial numbers</span>
<span class="hl-keyword">mkdir</span> <span class="hl-attribute">-p</span> serials

<span class="hl-comment"># Loop all domains, connect and fetch the serial</span>
for i in $(cat domains.txt); do
  <span class="hl-keyword">echo</span> <span class="hl-value">&quot;Connecting to $i ... &quot;</span>

  (
    openssl s_client <span class="hl-attribute">-connect</span> <span class="hl-variable">$i</span>:443 <span class="hl-attribute">-servername</span> <span class="hl-variable">$i</span> <span class="hl-attribute">-showcerts</span> &lt; /dev/null 2&gt; /dev/null |
    openssl x509 <span class="hl-attribute">-text</span> <span class="hl-attribute">-noout</span> |
    <span class="hl-keyword">grep</span> <span class="hl-attribute">-A</span> 1 <span class="hl-value">&quot;Serial Number&quot;</span> |
    tr <span class="hl-attribute">-d</span> : |
    tail <span class="hl-attribute">-n</span> 1
  ) | tee serials/<span class="hl-variable">$i</span>;

done
</pre>
<p>The <code>openssl s_client</code> connects to the domain (using Server Name Indication (SNI) with the <code>-servername</code> option) and lists all certificates.</p>
<p>Now, in <code>serials/*</code>, we have a directory full of domain names and their corresponding certificate serial.</p>
<h2 id="combining-all-serials">Combining all serials <a href="#combining-all-serials" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#combining-all-serials">#</a></h2>
<p>We'll make a single list with all the serials we need to check. This way, we can optimize our <code>grep</code> commands for later.</p>
<pre data-lang="bash" class="notranslate">$ <span class="hl-keyword">cat</span> serials/* | tr <span class="hl-attribute">-d</span> <span class="hl-value">&quot; &quot;</span> | sort | uniq &gt; serial-numbers.txt
</pre>
<p>The file <code>serial-numbers.txt</code> is now a gigantic list of serial numbers.</p>
<h2 id="finding-the-serials-in-the-12gb-text-file">Finding the serials in the 1.2GB text file <a href="#finding-the-serials-in-the-12gb-text-file" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#finding-the-serials-in-the-12gb-text-file">#</a></h2>
<p>Let's Encrypt has <a href="https://letsencrypt.org/caaproblem/">released a text-file with all affected certificates</a>. This file includes the Serial Number (which we now have) together with all domains/SANs on the certificate.</p>
<p>Our first attempt was to simply <code>grep</code> our way through the file for each serial found. But <code>grep</code> is single-threaded, so we could only utilize a single CPU core for searching through a pretty big file.</p>
<p>This was taking too long, so we quickly adapted our method and started to search through the log in parallel.</p>
<p>Lucky for us, we started preparing a new set of servers <a href="/features/broken-page-and-mixed-content-detection">for our crawlers</a> that check for broken links last week. Those servers were still idling as they aren't in production yet. This was the perfect time to use that spare capacity.</p>
<p>First, we split the big file of serials (called <code>serial-numbers.txt</code>) in many equal pieces.</p>
<pre data-lang="bash" class="notranslate">$ split <span class="hl-attribute">-l</span> 1000 serial-numbers.txt
</pre>
<p>This gives us a list of many files, all with 1000 serial numbers in it. The file naming is predictable:</p>
<pre data-lang="txt" class="notranslate">$ ls -l x*
-rw-rw-r-- 1 immutable immutable 2672 Mar  3 20:27 xaa
-rw-rw-r-- 1 immutable immutable 2948 Mar  3 20:27 xab
-rw-rw-r-- 1 immutable immutable 2948 Mar  3 20:27 xac
-rw-rw-r-- 1 immutable immutable 2960 Mar  3 20:27 xad
</pre>
<p>In order to utilize all our cores, we used each file as the pattern input to <code>grep</code> and sent the job to the background for processing.</p>
<pre data-lang="bash" class="notranslate">for file in $(ls x*); do
	\grep <span class="hl-attribute">-P</span> <span class="hl-value">&quot;$(cat $file | tr &quot;</span>\n<span class="hl-value">&quot; &quot;</span>|<span class="hl-value">&quot; | sed -e 's/|/\|/g' | sed -e 's/|$//' )&quot;</span> ../ssl-cert/caa-rechecking-incident-affected-serials.txt &gt;&gt; results.txt &amp;
done
</pre>
<p>That rather ugly-looking <code>tr</code> &amp; <code>sed</code> pipeline in there transforms the input file from a new-line separated list of serials, to a <code>|</code>-separated list. This is used in <code>grep</code> to indicate the &quot;or&quot; statement, any line may match.</p>
<p>In the long form, it turns our input of this:</p>
<pre data-lang="bash" class="notranslate">$ <span class="hl-keyword">cat</span> xaa
01009ba...
0111839...
011539e...
0135d43...
</pre>
<p>... into this:</p>
<pre data-lang="txt" class="notranslate">01009ba...|0111839...|011539e...|0135d43...
</pre>
<p>Because we sent each <code>grep</code> command to the background in our <code>for</code>-loop, using the <code>&amp;</code> at the end of the command, we now have many <code>grep</code>'s running in parallel.</p>
<p>What followed was, to me as a sysadmin, a thing of beauty. ?</p>
<p><img src="/uploads/blogs/letsencrypt-revocation-check/server-usage.png" alt="Server Utilization of the Lets Encrypt checks" /></p>
<p>The crunching continued for a while, and we now had a list of affected serials stored in <code>results.txt</code>.</p>
<p>At this point, things were getting a bit late, so we resorted to even <em>weirder Bashness</em> to match these serials back to the domain names.</p>
<h2 id="matching-the-serials-back-to-domains">Matching the serials back to domains <a href="#matching-the-serials-back-to-domains" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#matching-the-serials-back-to-domains">#</a></h2>
<p>We loop each affected serial and match it back to the domain:</p>
<pre data-lang="bash" class="notranslate">for line in $(cat results.txt ); do
	\grep <span class="hl-variable">$line</span> serials/*;
done |
	<span class="hl-keyword">awk</span> <span class="hl-value">'{print $1}'</span> |
	<span class="hl-keyword">sed</span> <span class="hl-value">'s/\// /'</span> |
	<span class="hl-keyword">awk</span> <span class="hl-value">'{print $2}'</span> |
	<span class="hl-keyword">sed</span> <span class="hl-value">'s/:/ /'</span> |
	<span class="hl-keyword">awk</span> <span class="hl-value">'{print $1}'</span>
</pre>
<p>Looking at it now, awake, it could've been much cleaner. But, it got the job done! We now have a list of domain names of clients we need to notify.</p>
<h2 id="sending-the-mails-to-clients">Sending the mails to clients <a href="#sending-the-mails-to-clients" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#sending-the-mails-to-clients">#</a></h2>
<p>To inform our clients, we resorted back to PHP. This allows us to send the notification e-mails in our own style/branding.</p>
<pre data-lang="php" class="notranslate"><span class="hl-type">Mail</span>::<span class="hl-property">to</span>(<span class="hl-variable">$users</span>)-&gt;<span class="hl-property">send</span>(<span class="hl-keyword">new</span> <span class="hl-type">LetsencryptRevokedMail</span>(<span class="hl-variable">$domain</span>));
</pre>
<p>It uses the power of <a href="https://laravel.com/docs/master/mail">Laravel Mailables</a> to make this really easy.</p>
<h2 id="a-rush-job-because-time-was-against-us">A rush job because time was against us <a href="#a-rush-job-because-time-was-against-us" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#a-rush-job-because-time-was-against-us">#</a></h2>
<p>We didn't do as a clean a job as we'd normally do. There were no tests, no clean integrations, and most of it was <em>hacked</em> together on very short-notice.</p>
<p>But, there wasn't much choice. The list of affected certificates was released yesterday, and within 48 hours the revocation was to take place. It was up to us to notify our users <em>asap</em>. After all, those affected still needed to renew their certificates!</p>
<p>We're happy to see the list of affected domains beforehand though. The normal procedure is that the revoced certificates end up in Certificate Revocation Lists (CRL), but at that point the revocation <em>has already happened</em>.</p>
<p>This allowed us to be proactive and inform clients ahead of time!</p>
]]>
            </summary>
                                    <updated>2020-03-04T07:41:06+00:00</updated>
        </entry>
            <entry>
            <title><![CDATA[Why agency Marbles chose Oh Dear for uptime monitoring]]></title>
            <link rel="alternate" href="https://ohdear.app/news-and-updates/why-full-service-agency-marbles-choose-oh-dear-for-its-uptime-monitoring" />
            <id>https://ohdear.app/13</id>
            <author>
                <name><![CDATA[Oh Dear]]></name>
            </author>
            <summary type="html">
                <![CDATA[<p>We reached out to one of our earliest customers, <a href="https://www.marbles.be/">Marbles</a>, to ask why they decided to move from Pingdom and use our service instead. If you're in doubt whether or not to give us a try, maybe they can convince you.</p>
<h2 id="our-interview-with-marbles">Our interview with Marbles <a href="#our-interview-with-marbles" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#our-interview-with-marbles">#</a></h2>
<h3 id="hi-rias-who-are-you-and-what-does-your-business-do">Hi Rias, who are you and what does your business do?</h3>
<p>We are <a href="https://www.marbles.be/">Marbles</a>, an Antwerp based full service agency that does everything from creating identities to marketing &amp; communications, business development and coaching. Of course creating websites and web applications is part of our services and to make sure they're the best they can be we use <em>Oh Dear!</em> for the monitoring.</p>
<h3 id="cool-why-did-you-chose-oh-dear-as-your-monitoring-solution">Cool! Why did you chose Oh Dear! as your monitoring solution?</h3>
<p>It includes all the checks we need for a very fair price.</p>
<h3 id="who-did-you-have-before">Who did you have before?</h3>
<p>We used Pingdom, but only for the basic uptime checks.</p>
<h3 id="what-made-you-switch">What made you switch?</h3>
<p>The detection of mixed content &amp; broken links and the https certificate expiration checks on top of the uptime monitoring.</p>
<h3 id="how-does-oh-dear-help-you-provide-better-service-for-your-clients">How does Oh Dear! help you provide better service for your clients?</h3>
<p>By alerting us of issues before anyone could possibly notice it manually. This allows us to fix issues before our clients are even aware of it, or if they are we can tell them we're already working on a fix.</p>
<h3 id="whats-your-favorite-feature-of-oh-dear">What's your favorite feature of Oh Dear?</h3>
<p>All the extra checks on top of basic uptime monitoring with Slack notifications and webhooks to receive reports.</p>
<h3 id="is-there-a-killer-feature-were-missing-that-could-help-you">Is there a killer feature we're missing that could help you?</h3>
<p>Setting up notification &quot;groups&quot;. We have clients who have an SLA with us, they need very quick solutions and we use the SMS notifications for them, for other clients we only set up the Slack Notifications.</p>
<p>It's bothersome to set up the SMS notifications individually for each site that needs them, and if another person needs to receive these, or the phone numbers need to get changed, we need to do this for each site manually.</p>
<p><em>In response: this is indeed a very good idea still missing, we're taking this up in our development to see if we can introduce an elegant solution to this problem. Thanks for letting us know!</em></p>
<h2 id="what-makes-oh-dear-special-to-you">What makes Oh Dear! special to you? <a href="#what-makes-oh-dear-special-to-you" class="heading-permalink" aria-label="Permalink" data-clipboard-text="https://ohdear.app/feed#what-makes-oh-dear-special-to-you">#</a></h2>
<p>We'll be reaching out to more of our customers over the next months to find out why they chose us over the (many) competitors out there. We'd love to know what pursuaded them and what items we still need to address to serve our customers even better.</p>
<p>If you want to share your thoughts, feel free to reach out to us on Twitter at <a href="https://twitter.com/ohdearapp">@OhDearApp</a>.</p>
]]>
            </summary>
                                    <updated>2026-06-15T12:38:26+00:00</updated>
        </entry>
    </feed>